01
Sources
Where: Data → Sources. Upload files, Import dataset (auto-mapping), or No documents yet? Write sample documents.
Inputs: a browser upload, or a source locator (jsonl:/path, hf:id:split, kaggle:competition:slug, etc.).
Outputs: rows on disk in the project's data dir.
Contract: source connectors implement load() + describe(). Unparseable rows surface as sentinel rows, not silent drops. A file that cannot be parsed is an error, never accepted text.
RunEvent: none here directly — the introspector + run downstream emit one each.
02
Introspect & map
Where: the import wizard behind Import dataset: Source → Task type → Map → Preview & Confirm.
Inputs: ~20 sample rows from the source; then locator + mapper + field map + optional drop reasons.
Outputs: ranked ShapeHypothesis list + a top ProposedMapping with confidence + rationale; on confirm, rows appended to the project's synthetic JSONL.
Contract: never silently auto-picks — below 0.80 the UI asks you to confirm you reviewed the proposal (CLI: --force). Per-row accountability: every row is a TransformedRow or a RejectedRow with a stable reason code; rejected rows are grouped by reason and bulk-droppable, and the counts stay in the audit row.
RunEvent: ingestion / dataset_import_run on success, dataset_import_failed on error. Payload: source, mapper, accepted/rejected counts, written_path, config_id.
03
Prepare
Where: Data → Prepare — chunk size, redact PII & secrets, Clean All Documents.
Inputs: the project's RawDocuments.
Outputs: cleaned text + chunks JSONL + per-document metadata (PII findings, quality score, text hash). Row files are cleaned row by row; only documents are chunked, on sentence boundaries.
Contract: runs as a background task that the notification bell follows, so the HTTP request never blocks.
RunEvent: cleaning / info on success; cleaning_outlier_threshold_exceeded / cleaning_pii_block on the named failure modes.
04
Labels
Where: Data → Labels — confirm the task shape ("What kind of task is this?") and build the answer key, the held-out set every score is measured against.
Inputs: your own labelled rows, rows drafted by a model and checked by a person, or (for span projects) labelling conventions, one line per type.
Outputs: a confirmed task profile + adapter preset that split, train and eval all read; the answer key (practice / final), kept out of training.
Contract: a leaked answer key makes a score measure memorisation, so train↔answer-key overlap is scanned and flagged.
RunEvent: none — labelling is data, not a run.
05
Generate
Where: Data → Generate — synthetic data: Single-turn Q&A, Multi-turn, or PII / NER span extraction; provider (local Ollama first, or a cloud model); playbooks matched to the task shape.
Inputs: cleaned passages (or pasted source text) + a generation model.
Outputs: rows in the project's synthetic JSONL, pending until accepted in the review queue (in the step's Details drawer).
Contract: pending and rejected rows never train. Offsets on span rows are verified against the text, never trusted. A batch that validates to nothing yields nothing and says why.
RunEvent: a background Job per batch; the bell reports rows kept and the diagnostic when none were.
06
Split
Where: Data → Split — train / validation / test, the dataset adapter, dedup, and Keep the current test examples on every later split.
Inputs: cleaned + accepted synthetic rows; the project's dataset-adapter preset.
Outputs: prepared/manifest.json + train.jsonl / val.jsonl / test.jsonl, plus a versioned snapshot of each split. Carries task_profile + output_schema.scoring_mode.
Contract: the manifest is the source of truth for everything downstream; nothing reads from disk paths directly. Keeping the test examples means a new run is scored on the same rows as the last one.
RunEvent: dataset-prep summary.
07
Train
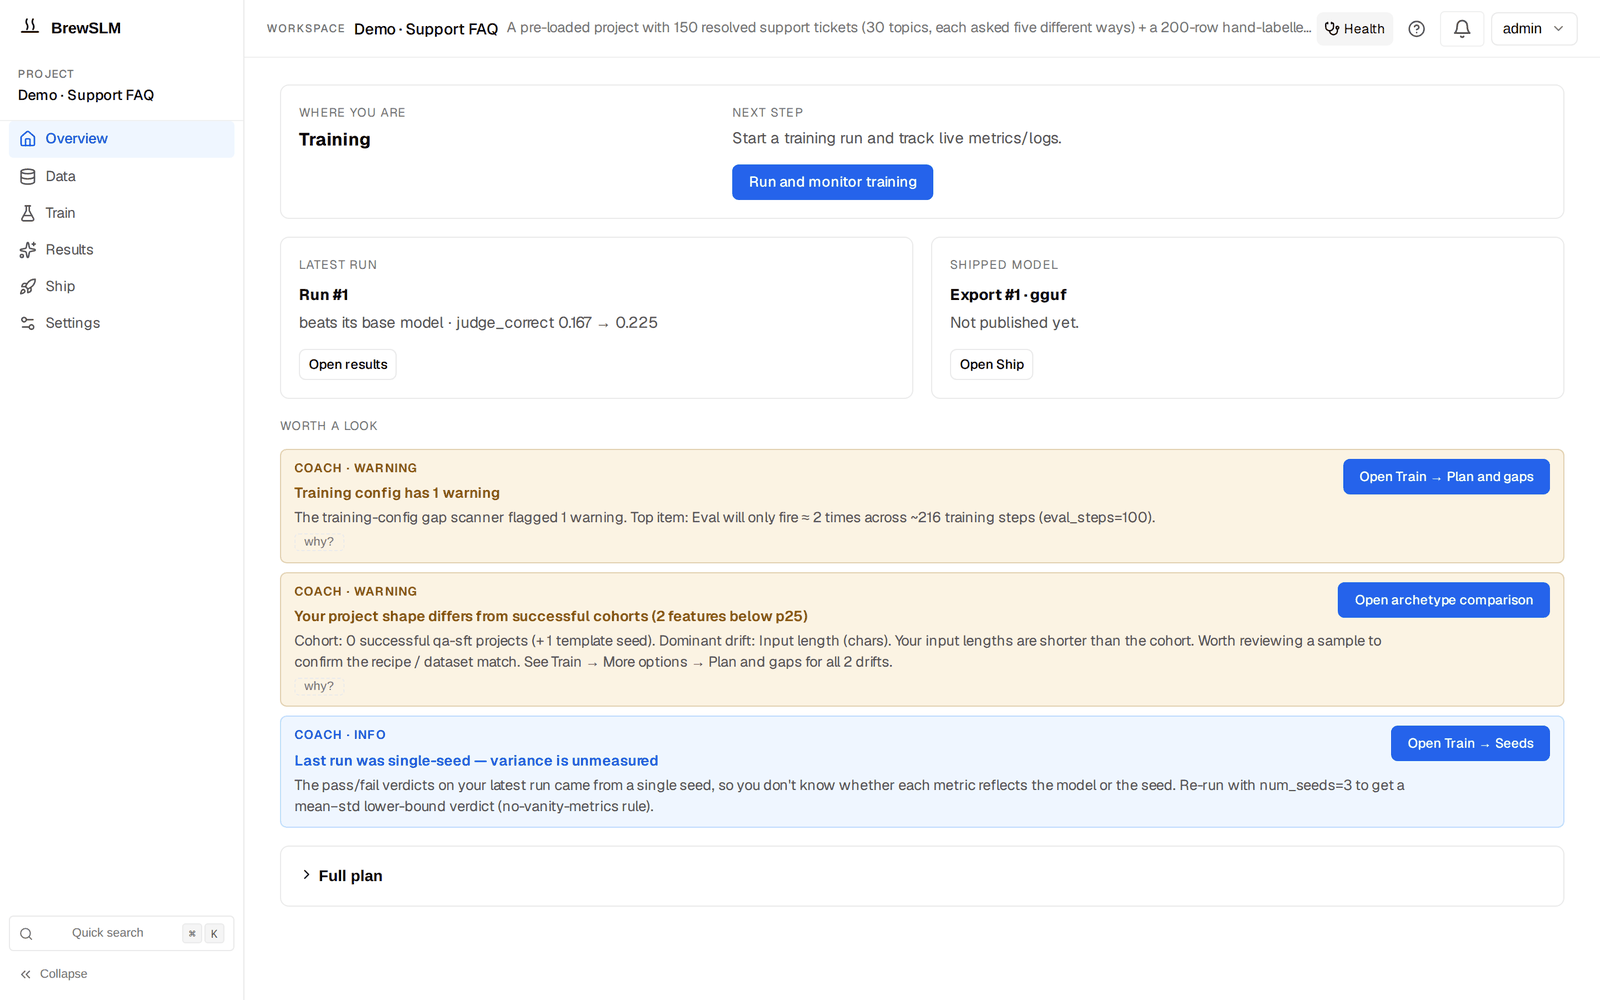
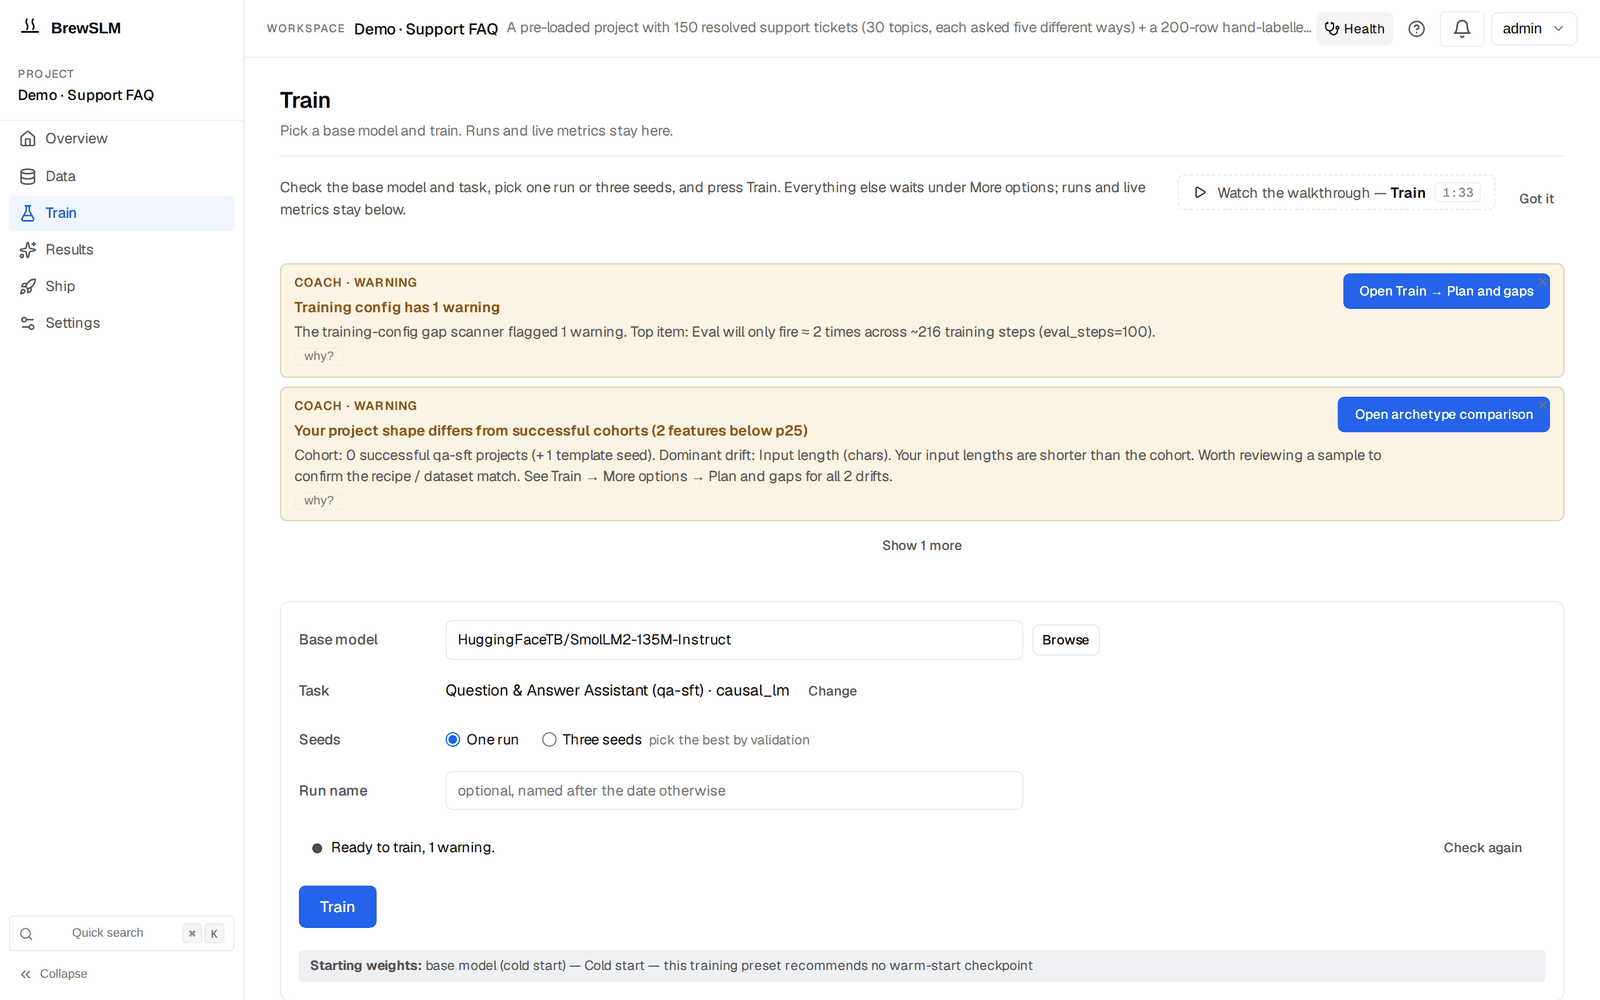
Where: Train — one form: base model (+ Browse), task, one run or three seeds, run name, a readiness line, and Train. Epochs, LoRA, checks, cloud burst, presets and the plan-vs-data gaps wait under More options. The runs list with each run's live dashboard sits below the form.
Inputs: prepared manifest + base model + the resolved config (shown in a confirm dialog with an estimate before Launch).
Outputs: checkpoints + per-step loss / eval traces + adapter weights (or a full model for encoders). Preflight runs first: dependency, memory-fit, capability and rule-policy checks; strict mode blocks, fail-open emits warnings.
Contract: task-handler dispatcher routes to ClassificationHandler, QAHandler, StructuredExtractionHandler (span_set or field_match), RAGHandler, AlignmentHandler, Seq2SeqHandler, VisionLanguageHandler, AudioTranscriptHandler, or SafetyHandler. Cancel stops the process.
RunEvent: training / info on completion (payload: experiment_id, backend, final_train_loss). training_oom / training_runtime_error / training_timeout / training_cancelled on failure.
08
Results
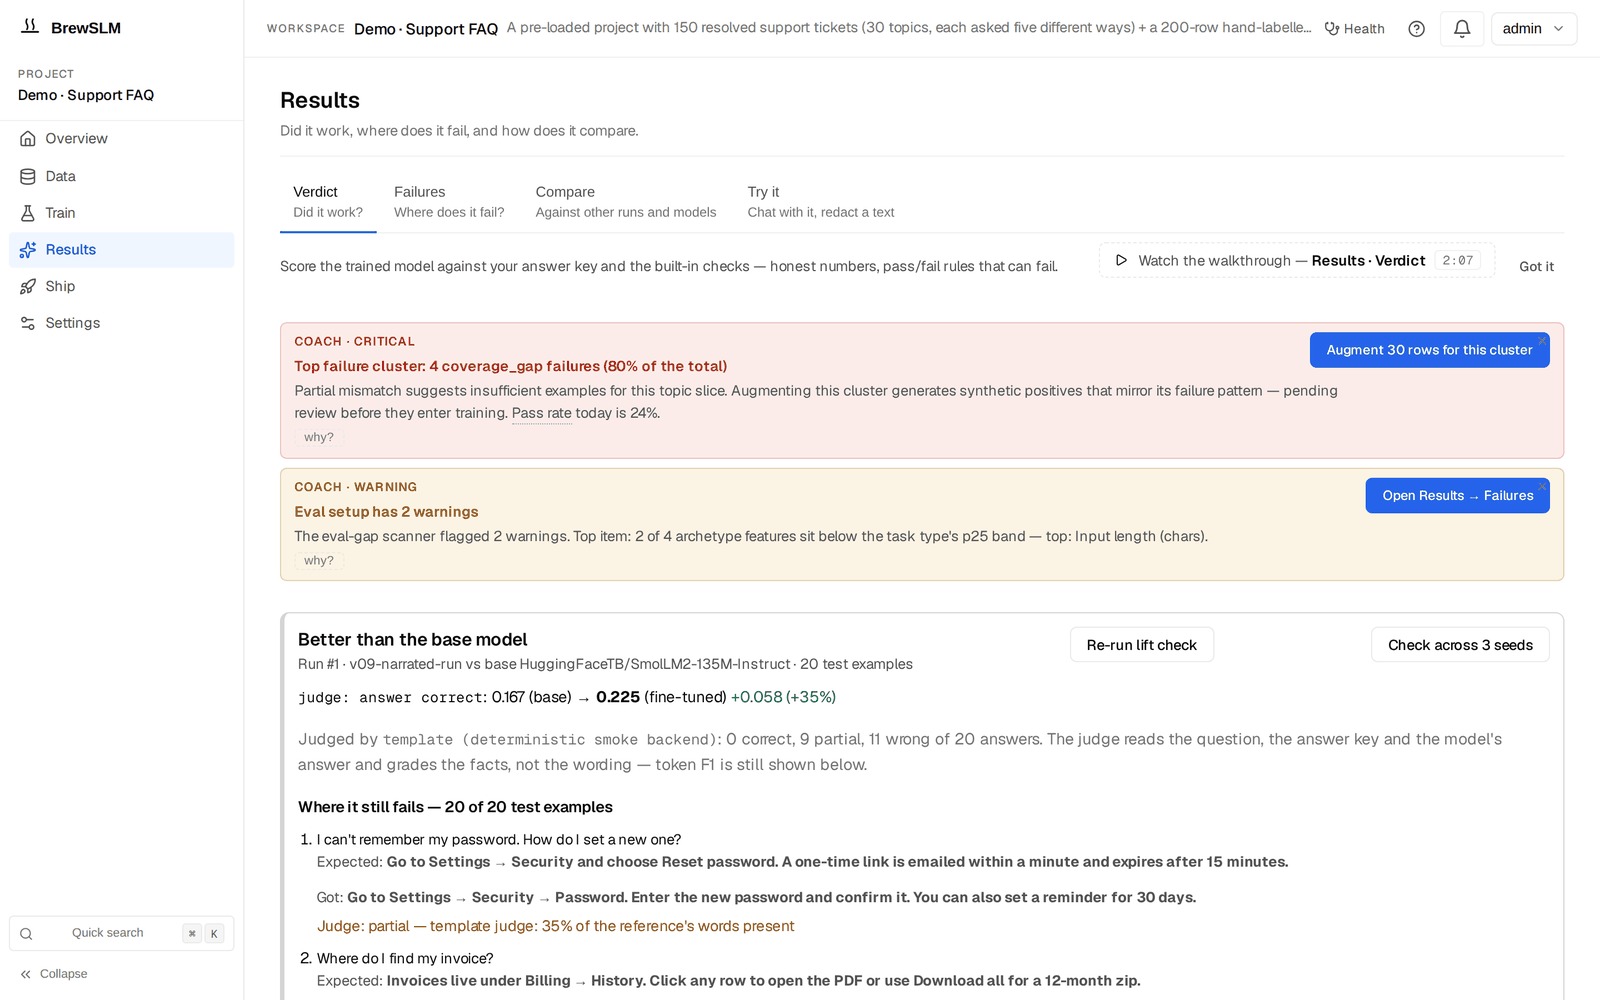
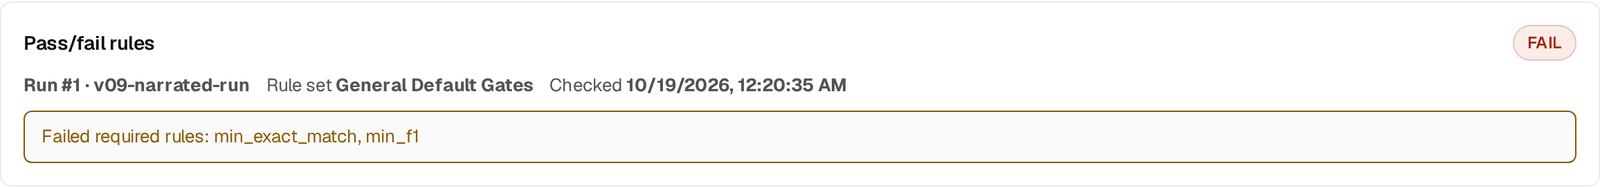
Where: Results — Verdict (did it work? the lift against the base model, pass/fail rules, the scorecard), Failures (where it fails: clusters, eval gaps, built-in and custom checks, slices), Compare (other runs, external benchmarks, Auto-RAG) and Try it (chat with the run; a redaction box for span runs).
Inputs: trained model + the test examples (or the answer key) + the rule set.
Outputs: task-aware metrics (per-class P/R/F1, span-set, faithfulness, alignment margin, BLEU/ROUGE, WER, etc.), paired base-vs-fine-tuned evidence (better / worse / within noise), and the pass/fail verdict.
Contract: the metric shape comes from the handler's score(); the pass/fail rules declared in the rule set decide promotability. The lift check runs by itself when a real run completes.
RunEvent: eval / info, parented to exp-<id>. eval_runtime_error / eval_judge_unavailable / eval_dataset_missing on failure.
09
Package & publish
Where: Ship → Package (New export: run, format, quantization, deployment targets; the Releases table; Options: Compress and the manifest) and Ship → Publish (a completed Hugging Face export to the Hub).
Inputs: trained model + target format (Hugging Face / GGUF / ONNX / Docker / vLLM-compat).
Outputs: artifact bundle with weights, tokenizer, manifest, smoke-check trace. A LoRA run is merged first.
Contract: quantization variants (Q4_K_M, AWQ, GPTQ) are tracked per run so a GGUF export packages only that run's compressed files — no raw-weights fallback under a compressed label.
RunEvent: export / info on success (payload: format, output_path, file_size_bytes). export_run_failed / export_artifact_missing / export_quantization_failed on the named failures.
10
Deploy & monitor (optional)
Where: Ship → Deploy (serve / deploy plans, served versions) and Ship → Monitor (run events, failure clusters, drift).
Inputs: an export + a target (vLLM endpoint / local runner / cloud burst).
Outputs: a versioned DeploymentVersion with promote / reject / rollback / drift-check actions.
Contract: smoke check at promote time; the drift check re-runs the answer key against the live endpoint on a schedule.
RunEvent: deployment / info per action; deployment_smoke_failed / deployment_drift_detected / deployment_promote_blocked on failure.