Evaluate: eval packs, gates, failure clusters & remediation
After this lesson you can read an eval pack's gates as the quality bar from Track 1, interpret task-aware metrics, and use failure clusters and remediation plans to decide what data to fix — the scaled-up version of your by-hand failure analysis.
In lesson 2.7 you ran a gold set by hand, computed accuracy, compared to the base, and read the misses to decide what data to fix. Stage 09 is that whole loop as a platform surface — with the quality gate from Track 1 made enforceable. In the workspace it lives under Results (/project/<id>/results): Verdict answers "did it work?", Failures answers "where does it fail?".
The eval pack and its gates
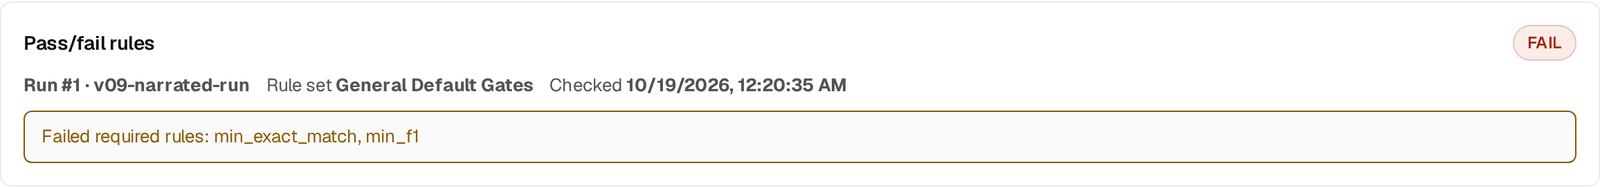
Evaluate takes the trained model, the held-out test split (the manifest's test.jsonl — the test examples in the UI), and an eval pack. The eval pack declares the metrics to compute and the gates that decide promotability — the pass thresholds a model must clear to be shippable. This is precisely the Track 1 quality gate, now a declared object the platform enforces rather than a number you remember to check. The UI calls the pack a rule set and its gates pass/fail rules (the API, the pack ids such as evalpack.general.default and the JSON keys keep the old names): Results → Verdict shows a Pass/fail rules card with the run, the rule set, when it was checked and which required rules failed; Results → Failures has the rule-set card where you pick the project's rule set and review each rule for the selected run.
eval_pack:
  metrics: [accuracy, macro_f1]
  gates:
    - metric: accuracy   min: 0.90      # must clear to promote
    - metric: macro_f1   min: 0.85
  compare_to: baseline                  # report lift over the base model
Task-aware metrics
You computed accuracy because yours was a classification task. BrewSLM computes whatever the handler's score() defines for the task shape — so the metric fits the task automatically:
classification   →  per-class precision / recall / F1, accuracy
extraction       →  span-set / field-match scores
RAG              →  faithfulness
alignment        →  preference margin
seq2seq          →  BLEU / ROUGE
transcription    →  WER
The result is a pass rate plus task-aware metrics, emitted as an eval RunEvent parented to the experiment (exp-<id>), with named failures like eval_dataset_missing or eval_judge_unavailable.
Failure clusters — your misses, grouped
Reading individual wrong predictions (what you did by hand) doesn't scale to thousands of eval rows. BrewSLM groups the failures into failure clusters: buckets of misses that share a pattern — a confused class pair, a particular input phrasing, an edge case the data underrepresents. Instead of skimming a list, you see "37 failures: negative reviews containing the word 'but'." Eval clusters sit on Results → Failures (with the remediation planner and the slice breakdown); failures from production run events are clustered on Ship → Monitor.
From Track 2
Your failure-analysis loop ("which misses tell me what data to add?") is exactly this — clusters just do the grouping so the signal is obvious. Each cluster is a concrete instruction for the next data iteration.
Remediation — close the loop
Each cluster comes with a remediation plan: the recommended fix, often "augment from this cluster" — generate or import more rows like the ones failing, route them through the review queue (lesson 3.3), re-split, and re-train. This is the augment_from_cluster action — the Augment N rows for this cluster button on the Coach notice at the top of Results, or Augment from this cluster on a cluster card under Results → Failures — and it's the data-centric iteration of Track 1 turned into a button. If the model cleared the pass/fail rules, it's promotable. If it didn't — and especially if more data won't fix it — the platform's next move is to ask whether fine-tuning is even the right tool, which is the next lesson.
Key idea
An eval pack (the UI's rule set of pass/fail rules) turns the Track 1 quality gate into an enforceable promotability check; task-aware metrics fit the task automatically; failure clusters + remediation turn your by-hand 'read the misses' loop into grouped, actionable next steps.
Key terms
- eval pack
- The declared set of metrics and promotion gates evaluated against the held-out test examples. In the UI: the rule set (Results → Verdict and Results → Failures).
- promotability gate
- A pass threshold in the eval pack a model must clear to be shippable (the Track 1 quality gate). In the UI: a pass/fail rule.
- task-aware metrics
- Metrics defined by the handler's score() to fit the task shape (F1, span-set, faithfulness, WER, …).
- failure cluster
- A bucket of eval misses sharing a pattern, surfaced instead of a flat list.
- remediation plan
- The recommended fix for a cluster — often augment_from_cluster to add similar rows and re-train (Results → Failures).
Check yourself
Answers are saved to this browser.