Train: jobs, the bell, and the delta-from-baseline curve
After this lesson you can launch training from the Train form as a background Job, monitor it via the notification bell and the run's live dashboard, read the delta-from-baseline view, and recognize the named training failure events.
This is the stage you know best — it's trainer.train() from lesson 2.5. The difference is everything around the loop: it runs as a tracked Job, streams progress to a bell, and plots its loss against your baseline.
Launch — one click or one call
In the workspace the launch is the Train page (/project/<id>/train): one form — base model, task, one run or three seeds, an optional run name, the readiness line — and the Train button, which opens a confirm dialog with the resolved config and an estimate before Launch. Everything else (epochs, LoRA, presets, cloud burst) waits under More options. Scripted, the same thing is two calls — create the experiment, then start it:
$ curl -X POST localhost:8000/api/projects/1/training/experiments \
    -H 'Content-Type: application/json' \
    -d '{"name": "run-2026-10-18", "config": {}}'      # → {"id": 42, ...}
$ curl -X POST localhost:8000/api/projects/1/training/experiments/42/start

# or let the Autopilot pick the plan from plain-language intent:
$ curl -X POST localhost:8000/api/projects/1/training/autopilot/one-click-run \
    -H 'Content-Type: application/json' \
    -d '{"intent": "classify support tickets by topic"}'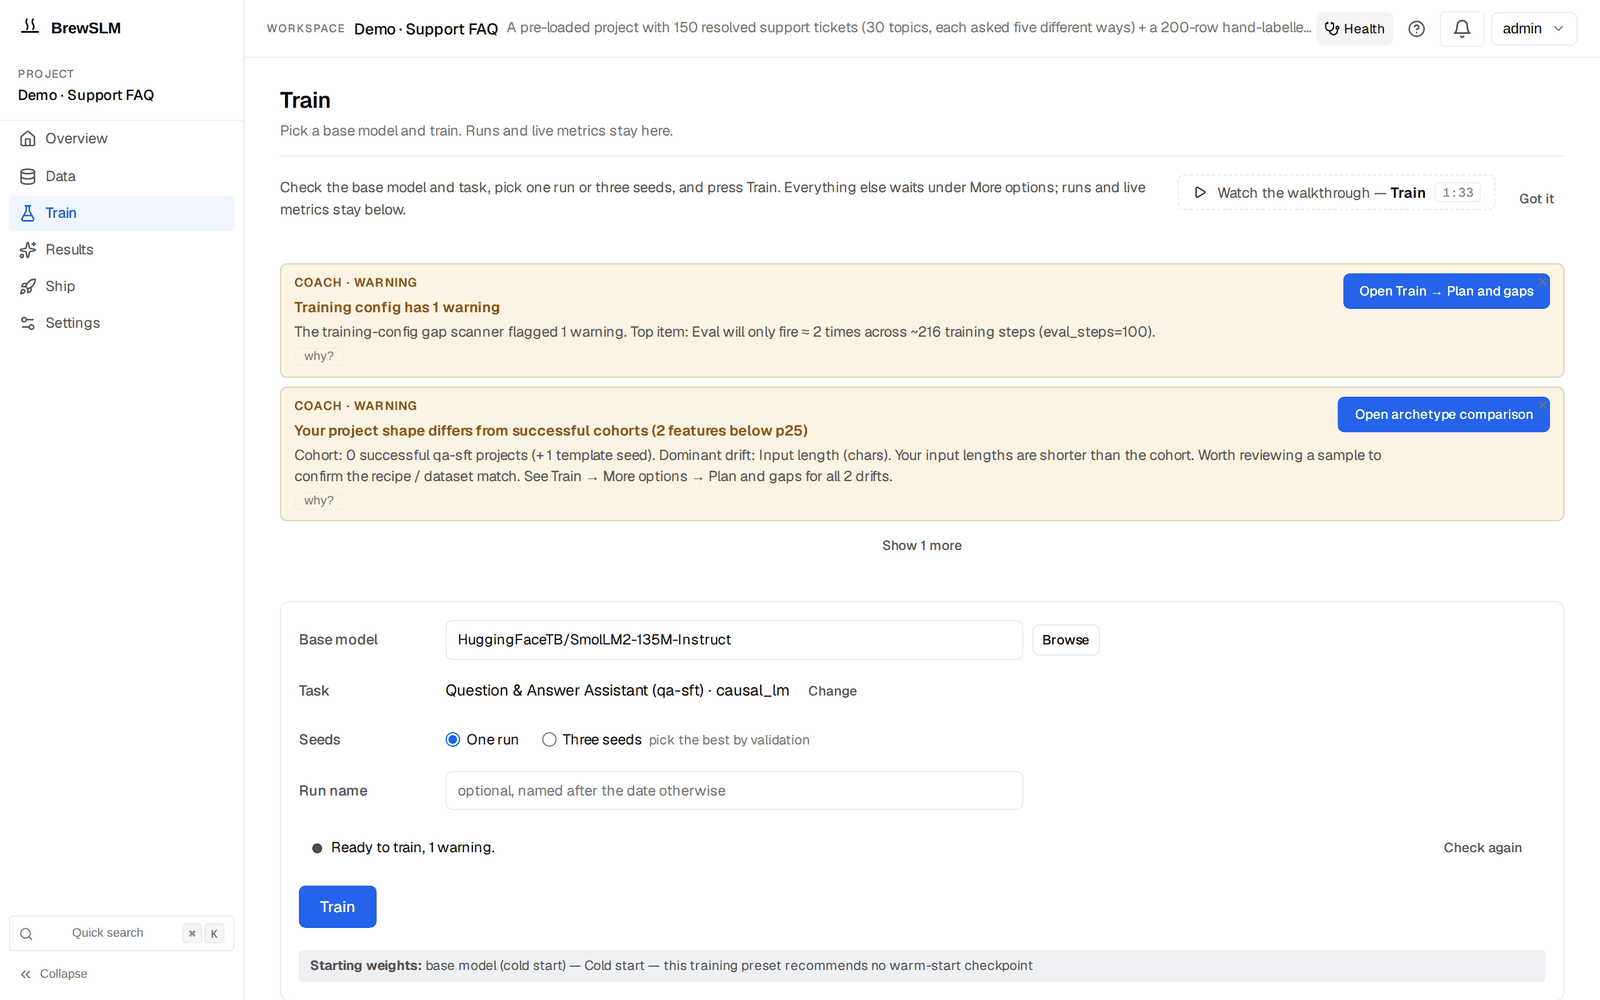
Training takes the prepared manifest + chosen recipe + checkpoint cadence, and produces checkpoints, per-step loss / eval traces, and a final adapter weights blob — the same outputs your Trainer wrote to sft-out/, now first-class records on the experiment.
It runs as a background Job
Long-running work in BrewSLM is a Job persisted to a table. The top-bar notification bell polls /api/jobs/active every ~4 seconds and surfaces progress and outcome, so you don't sit watching a terminal. A watcher Job mirrors the experiment's progress into the bell, and the Job framework holds a strong reference to the running task so it can't be silently garbage-collected mid-run. The run itself appears in the runs list under the Train form, with its live metrics; when it completes, the watcher starts the lift check that Results → Verdict reports.
The delta-from-baseline curve
In Track 2 you read raw loss numbers scrolling past. On a run's dashboard BrewSLM plots the live loss curve, and for a warm-started run (one that continues from a checkpoint) it adds a delta from baseline series — the checkpoint's first recorded loss on your data is the zero line, and the run is drawn relative to it, so the marginal contribution of your rows is legible. That reframes the question from "is 0.58 good?" (which you can't judge in isolation) to "am I beating the starting point, and by how much?" — the comparison Track 1's evaluation lesson insisted on, now live during training. The base-model comparison proper comes after the run: the automatic lift check scores the base model and the fine-tune on the same test examples, and Results → Verdict (and the Overview's Latest run card) says whether the run beats its base and by how much.
From Track 2
Everything you learned about reading curves (lesson 2.6) applies here — falling-and-flattening is healthy, a rising eval trace is overfitting. The delta-from-baseline view just makes "better than where the checkpoint started" the explicit y-axis.
Completion and failure are events
When the run finishes it emits training / info with a payload of experiment_id, backend, and final_train_loss. When it fails, it emits a named event so you know exactly what happened:
training            (info)     # completed: experiment_id, backend, final_train_loss
training_oom                   # ran out of GPU memory
training_runtime_error         # crashed mid-run
training_timeout               # exceeded the time budget
training_cancelled             # you cancelled it
Those map directly onto the failure modes you learned to diagnose by hand — but now they're typed, logged, and visible in the run events and failure clusters under Ship → Monitor rather than buried in a stack trace. Cancelling a run from its row stops the training process itself. With a trained adapter and its traces recorded, the next stage asks the real question: is it good enough to ship? That's evaluation — Results.
Key idea
Stage 08 is your training loop, watched: one Train form, a background Job with bell progress, a live dashboard per run (with a delta-from-baseline curve for warm starts), an automatic base-vs-fine-tune lift check on completion, and named RunEvents for completion and every failure mode.
Key terms
- training Job
- The background, persisted task that runs stage 08, launched from the Train form; tracked so it can't be GC'd mid-run.
- NotificationBell
- Top-bar surface polling /api/jobs/active (~every 4s) for progress and outcome.
- delta-from-baseline curve
- On a warm-started run's dashboard: the live loss plotted relative to the checkpoint's first recorded loss on your data as the zero line.
- training RunEvents
- Named events: training (info) on completion; training_oom / _runtime_error / _timeout / _cancelled on failure.
Check yourself
Answers are saved to this browser.